Browser NLA: Moving the Agent Loop Inside the Browser
In short: Most AI browser agents sit outside the browser, round-tripping screenshots and HTML over the network. Browser NLA moves the planning, execution, and deterministic self-repair loop directly inside the browser engine, now backed by System 1 decision models.
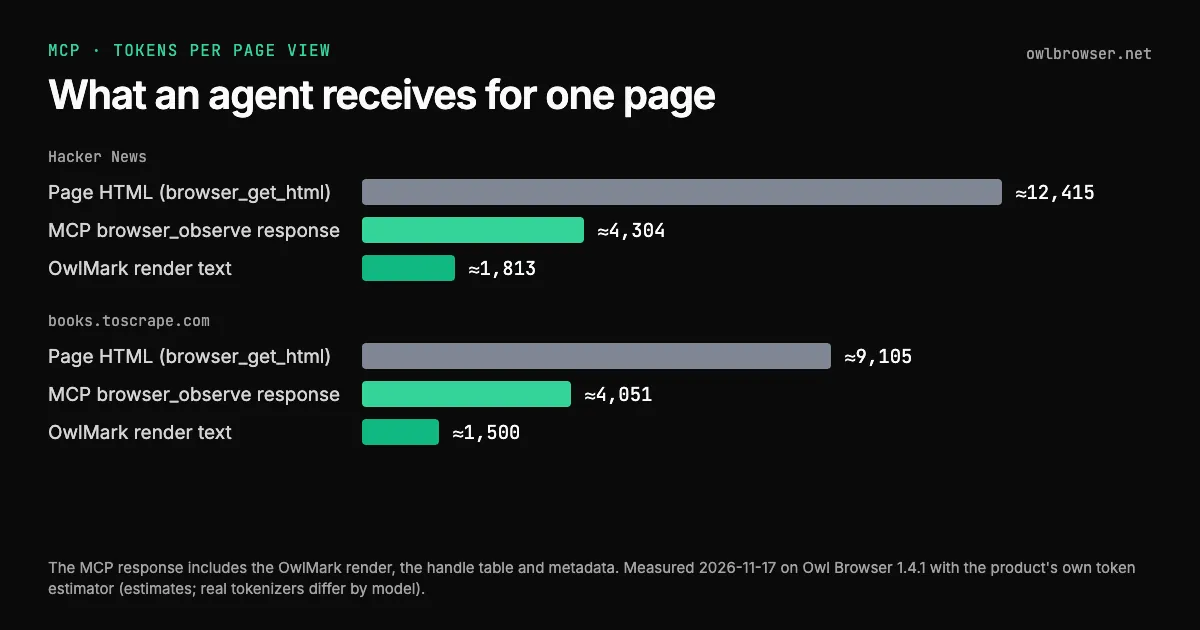
Most browser automation setups built on language models follow the same external architecture: your Python or Node process holds the model client, calls an API to capture a screenshot or dump the DOM, passes the payload to an LLM, parses the response, and sends a click or keypress back over the wire. Every step requires a high-latency network round trip, and on every step the model must reconstruct its spatial and functional understanding of the page from scratch.
Browser NLA (Natural Language Automation) takes a different approach by moving the entire agent loop directly inside the browser process. You send a single command and a context identifier. The browser inspects the live accessibility tree, plans the sequence, executes actions against stable element handles, checks its own work, and handles unexpected obstacles in-process until the goal is achieved.
Architectural Advantages of In-Engine Automation Loops
Running the agent loop alongside the DOM and CEF rendering pipeline avoids several failure modes that are common when an agent drives a browser from the outside:
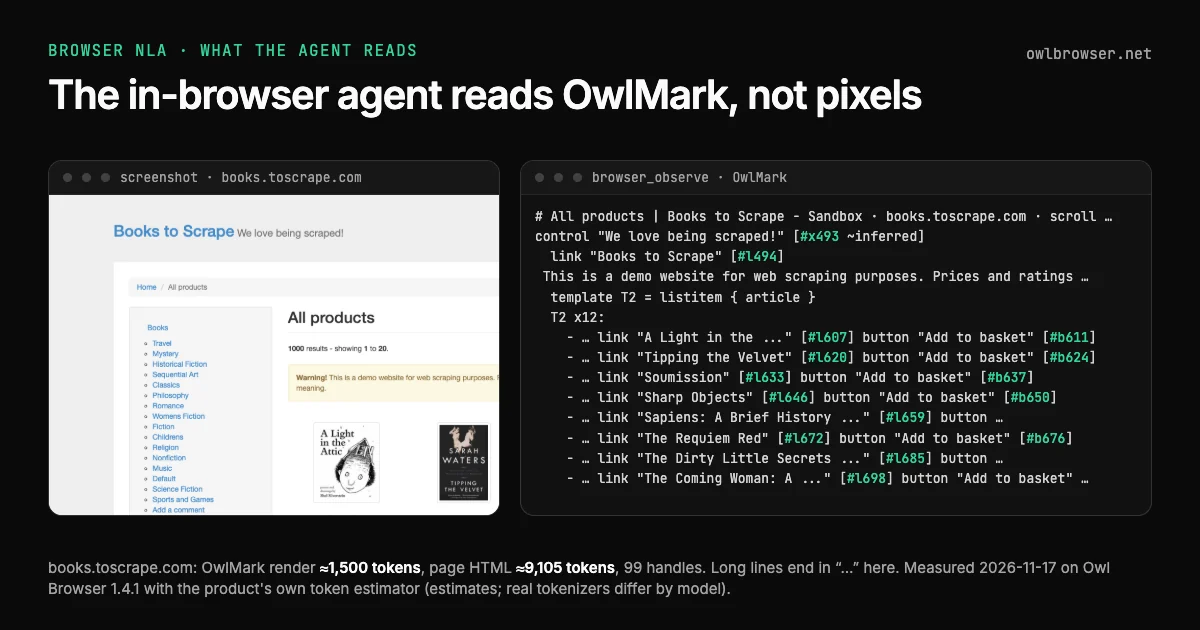
- Perception from the accessibility tree: NLA reads OwlMark, a compact handle-addressable render derived from layout geometry and accessibility nodes. Elements receive stable tokens like b3 and l12. The model refers to concrete controls rather than guessing pixel coordinates.
- Pre-execution action validation: Every proposed action is verified against the engine's active handle table before running. If a model hallucinates an invalid element identifier, the action is rejected locally with zero browser round trips.
- Deterministic mechanical repair: Cookie banners, popups, stale handles, off-screen scrolling, and links opening new tabs are handled by deterministic recovery routines in code rather than burning model reasoning turns on routine obstacles.
- Anti-loop escalation: When an action fails repeatedly, NLA suppresses the action, informs the planner, and forces route escalation instead of burning token budget in an infinite retry loop.
- Live evidence-based planning: Milestones track concrete page states. A milestone advances only when the page demonstrates verifiable proof of completion, and the plan dynamically rewrites when a route is blocked.
Running an NLA Task
NLA runs against a model endpoint you configure: any OpenAI-compatible API (vLLM, LM Studio, Ollama, OpenAI, or a hosted gateway). The model configuration is attached to the browser context when you create it:
curl -X POST "$OWL/execute/browser_create_context" \
  -H "Authorization: Bearer $TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
        "render_mode": "agent",
        "llm_enabled": true,
        "llm_endpoint": "https://your-model-gateway/v1",
        "llm_model": "your-model-name",
        "llm_api_key": "your-key"
      }'
Once the context exists, you dispatch commands to browser_nla:
curl -X POST "$OWL/execute/browser_nla" \
  -H "Authorization: Bearer $TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
        "context_id": "ctx_0001",
        "command": "Search for noise cancelling headphones, filter by price under 150, and extract the title of the top three items"
      }'
Because complex multi-step workflows take time, NLA tasks run asynchronously. You can inspect live progress with browser_nla_status, track the current phase and active step, or halt execution cleanly using browser_nla_cancel.
System 1 Model Integration in Version 1.4.0
In version 1.4.0, NLA adds native support for System 1 constrained-decision models. In an automation loop, the model performs four distinct functions: planning a route, deciding the next action on the current page, verifying whether the action succeeded, and extracting the final answer.
Measuring real runs showed where the cost goes. The per-step decision and verification calls account for most of the spend; verification alone was 17.9% of tokens, and 93% of verification calls (169 of 181) found nothing wrong. And 78% of action decisions selected exactly one action from the current page.
System 1 models are purpose-built for this exact shape. Instead of paying generative token costs to emit text on every step, NLA maps live page elements into closed candidate choices evaluated by the System 1 backend. A generative model can still establish high-level milestones, while the System 1 model drives fast, bounded action selection and verification without hallucinating selectors.
Structured Step Lifecycle
Every step in the NLA lifecycle follows an explicit six-stage progression:
plan -> observe -> decide -> validate -> act -> verify
           ^                    |                 |
           |                (invalid)          (failed)
           |                    v                 v
           +------------- recover or escalate ----+
Decisions enforce strict JSON schemas requiring the reasoning step to decode before the action verb. This prevents output runaway on complex pages and guarantees that actions are bounded to valid verbs: click, type, navigate, scroll, select, and form submission.
Getting Started
Browser NLA is included in Owl Browser 1.4.0 and later. You can start it through the REST API (browser_nla, then browser_nla_status and browser_nla_cancel) or from the Python and TypeScript SDKs. For long-running flows, start it with submit_job / submitJob in the SDK and poll the job for status.
How we test it
Every Owl Browser release has to pass an NLA flow in our end-to-end release suite, run against a freshly built server. In it, browser_nla collects and compares all five pages of a test catalogue, recovers from a dead data feed by using a cached mirror, reads a report behind a consent gate without taking either paid accept route (the flow then checks the agent never reached the charged page), and follows a link that opens in a new tab. A release with a failing flow does not ship.
Update (Nov 2026)
On Owl Browser 1.4.1, browser_nla is a REST and SDK tool; it is not part of any MCP tool profile. The NLA measurements above come from our internal NLA test runs before the 1.4.0 release.
About the author
Akram Hasan Sharkar, Founder & CTO at Olib AI
Previously Lead Software Developer at Aloha, with over 14 years of systems engineering experience. Akram founded Olib AI and architects Owl Browser's custom C++ Chromium and Blink engine, source-level fingerprint virtualization, Agent Rendering (OwlMark), and MCP automation stack.